Turning Implicit User Signals Into Agent Improvement Backlog Items
Behavioral signals from production traces reveal agent failures that users never explicitly report.
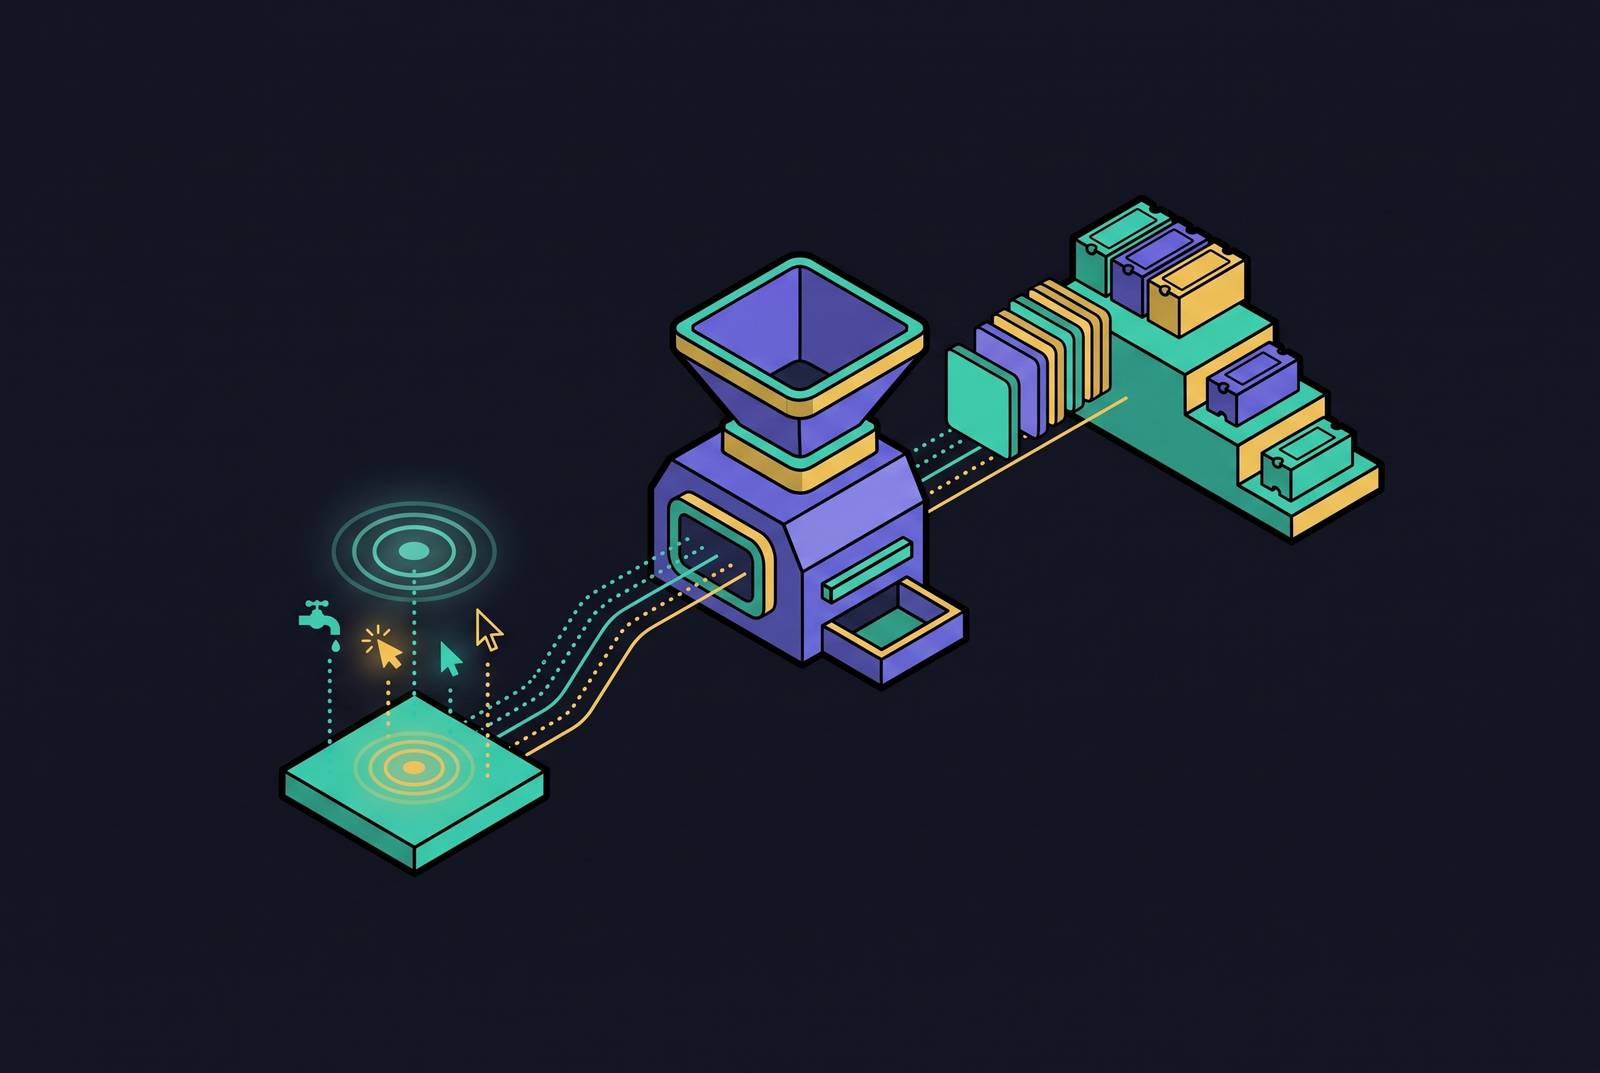
Production agents generate hundreds of sessions a day, and almost none of that behavior turns into a fix. Engineering teams can see the traces, but the traces sit in storage unread because no pipeline converts raw behavior into something a developer can act on. The fix is a disciplined process that reads implicit signals from traces, attributes each one to the exact harness layer that caused it, and turns the diagnosis into a backlog item with a replay set attached, closing the loop between production agent observability and the next shipped improvement.
The Gap Between User Behavior and Agent Improvement
Most teams running agents in production sit on logs of every session their users ran, but they have no meaningful feedback data from those users. Thumbs-up and thumbs-down buttons capture only a sliver of actual sentiment, because most users never click either one. Behavioral signals, by contrast, leak preference continuously: a user who retries a request, rewords a question, or quietly abandons a task midway is expressing a judgment about the agent's output whether or not any button gets pressed. Research on implicit feedback in human-LLM dialogues confirms that these behavioral traces are a genuine lens into what users want, but also that the raw signal is noisy enough that it cannot drive model improvement on its own. Part of that noise is structural: the value of implicit feedback tracks the quality of the user's original prompt, and the signal gets harder to read as queries grow longer and more complex, which describes most of the work production agents are actually deployed to do. User preferences also rarely get stated explicitly. They evolve across a session and stay embedded in long interaction histories, so even if a team reads every log, it still has to synthesize what it finds on top of collecting it. None of this is a reason to discard implicit signals. It is the reason they need a pipeline, one that attributes each signal to a cause and converts it into a structured backlog item instead of feeding raw behavioral noise into a loop that cannot use it.
Which implicit signals are worth instrumenting for
Retries, rephrasing, abandoned flows, and mid-task corrections are the four behavioral events worth instrumenting for, because each leaves a distinct fingerprint in a trace and points at a specific class of failure. A retry is the user resubmitting the same or nearly the same request, visible in a trace as a repeated tool invocation or a duplicate turn inside one session, and it means the agent's first answer did not satisfy the goal. Rephrasing is a follow-up turn where the user reformulates the request, and the content of that follow-up, what the user was trying to clarify, carries more diagnostic weight than the bare fact that a follow-up happened. Abandoned flows are sessions that end before task completion with no explicit error attached, just a user who stopped, and they are the hardest of the four to detect without spans scoped to the full session rather than a single turn. A mid-task correction happens when a user interrupts a multi-step run to redirect the agent, and since agents often fail to connect earlier context to a current request unless prompted, it is usually a sign of a memory or planning failure, not a one-off misunderstanding. None of these four are events a user deliberately fires the way they would a feedback button. They have to be derived from span sequences: turn counts, session termination without a completion event, repeated argument values across consecutive tool calls. That derivation requirement is the design constraint for instrumentation. If a signal cannot be reconstructed from span data, it does not belong on this list.
What a production trace must contain to make these signals readable
None of the four signals above are readable from basic request-response logging. Detecting them requires hierarchical spans carrying business metadata, plus enough intermediate state to distinguish a planning failure from a tool failure from a prompt failure. Agent observability has to capture intent and process, not just inputs and outputs: the reasoning trace, the tools considered versus the tools actually invoked, the arguments passed, the responses returned, the tokens spent, and the latency of each hop, all stitched into one hierarchical structure that can be replayed later. Structured attributes on each span, things like user_id, session_id, and strategy_id, let a team filter thousands of traces down to a failure pattern that no single trace would reveal in isolation. Without those tags, a team can replay exactly one failing trace at a time; with them, a team can replay a class of failures. Session scope matters most for abandoned flows, because to detect one you need a session_id that groups every related span together so the system can check whether a completion event was ever emitted. A span that closes with no completion event is the signal itself. Consider rephrasing as a worked case: in a well-structured trace, a rephrased turn appears as two consecutive user turns within one session_id, with the second turn's arguments differing from the first in a way that's attributable to a specific tool call or prompt section. In a poorly structured trace with no session grouping and no turn index, that same rephrasing looks like two unrelated requests from the same user, and the pattern disappears. Agents also fail silently, without exceptions or bad status codes, so a trace schema built only to catch errors will miss most of what matters. The minimum viable schema for signal detection includes turn index, session_id, tool name, arguments passed, return value, token count, latency per hop, a completion boolean, and a structured error field that distinguishes an exception that was caught from a case where nothing was thrown and the output was simply wrong.
Attributing a captured signal to the harness layer that caused it
A captured signal only becomes actionable once it is attributed to a specific harness layer, prompt, tool, workflow, or memory, because attribution is what determines who owns the fix and what part of the system actually has to change. An outcome-level signal like "this execution failed" offers almost no diagnostic value on its own. Root-cause attribution is what turns that outcome into something a developer can act on, by assigning the fault to the model, the harness, the environment, or the grader responsible for it. Misattribution at scale carries a real cost: it sends engineers chasing the wrong fix and can trigger interventions that solve nothing while the actual failure keeps recurring. Some attribution follows directly from signal type. A retry that follows a tool call should prompt you to check the tool arguments against the schema; if a required argument is missing and the resulting exception gets silently swallowed, that is a tool-layer failure, not a prompt problem. If a mid-task correction has the user re-state context the agent should already have, that is a memory failure, specifically a failure to retrieve or synthesize a relevant prior state. Tool schema drift is the case worth walking through in full, because it shows how badly attribution can go wrong without trace-level inspection. The model still operates on the tool contract it learned yesterday, but the system now enforces a contract that changed today. A cached planner emits the old field name. The runtime adapter maps that missing required field to null. A retry layer interprets the resulting failure as temporary and resubmits the same bad call. When the retries fail too, a fallback handler switches over to a search tool. At no point does anything crash visibly. What engineers see instead is an agent that has become flaky, with no single trace making the cause obvious, because the actual defect is a field name mismatch buried three layers deep in the call stack. Version drift deserves a brief mention as a confound to rule out before attributing a regression to a prompt or tool change: sometimes the code and prompts haven't moved at all, and the output shifted because the underlying model provider updated the weights. That possibility has to be checked and set aside before attribution proceeds, but it is not itself a primary target for this kind of harness-layer diagnosis. In every case, attribution confidence depends on recurrence. A single trace is rarely enough to act on; the same span signature needs to appear across multiple traces before you can call the pattern solid enough to justify a backlog item. Converting raw behavioral noise into structured improvement work requires exactly this kind of systematic attribution step, and platforms like Moda operationalize it by ingesting production traces and automatically surfacing which harness layer, prompt, tool, workflow, or memory, each implicit signal points to, so the diagnosis is attached to the signal before it ever reaches a backlog.
Anatomy of a Well-Formed Backlog Item
An attributed failure becomes useful when it's written down with enough specificity that a developer can reproduce it, fix it, and check the fix against the traces that exposed it. Anything short of that is a hunch sitting in a ticket queue. A well-formed backlog item carries five fields. The signal field names the implicit signal type, whether retry, rephrasing, abandoned flow, or mid-task correction, along with the session IDs and trace IDs where it was observed and how often the pattern recurs across sessions. The attribution field names the harness layer responsible, prompt, tool, workflow, or memory, and the specific component inside that layer, something as precise as the arguments field of a search_inventory tool schema that was updated on a given date and no longer accepts the legacy item_id field the planner is still emitting. The reproduction field provides the minimal trace or trace segment that reliably reproduces the failure, exportable so production failures can be turned into eval cases with one click, which is what closes the loop between a real-world failure and the CI test suite that should have caught it. The proposed fix field describes a concrete, reviewable change to the harness, a revised prompt snippet, an updated tool schema, a new exit condition in a workflow, a memory retrieval rule, never a vague directive to retrain the model. And the validation criterion field lists the historical traces the fix has to pass before anyone ships it, so the item doesn't close until the proposed change has been replayed against that set. The reviewability of the proposed fix matters as much as its content, because engineers need to see what changed and why rather than accept a recommendation as a black box; the backlog item has to expose the diff, not just the outcome. The tool schema drift case from the previous section shows what this looks like fully filled in: retries spiked after a schema version changed, and the backlog item names that version change, the affected span, the old and new field names, the specific prompt section still referencing the old field, and the three sessions whose traces will serve as the replay set once a fix is proposed. Because harness updates can break behavior that was previously working even when the underlying model hasn't moved, the validation criterion has to include regression traces alongside the failing ones that motivated the item. Any backlog item missing a reproduction trace or a validation criterion should go back to triage, since without those two fields nobody can close it with any real confidence.
Validating the proposed fix before it ships: replay against the traces that exposed the failure
If you ship a harness change without replaying it against the production traces that exposed the original failure, you are shipping on faith. The only honest confidence check is whether the fix eliminates the failure pattern in the sessions where it was observed without breaking sessions where the agent was already working correctly. Replay means recorded tool outputs combined with sandboxed side effects, and that is what separates stable and cheap agent testing from a test suite that looks rigorous but behaves unpredictably from run to run. A research artifact called Chronicle, published in September 2026 under arXiv:2609.20625, formalizes cut-point replay specifically for regression testing of LLM agents, giving this kind of validation a technical grounding beyond ad hoc scripting. To build the replay set, take the failing traces that motivated the backlog item as the positive set the fix must resolve, and pair that with a stratified sample of passing traces as the regression set the fix must not disturb. The validation criterion field from the backlog item gets satisfied this way: the field names the traces, and replay is the mechanism that checks the fix against them. An eval suite built only from failures someone thought to write down in advance will always lag behind production, because production invents failure modes nobody anticipated. Exporting every investigated failure as a permanent regression gate keeps the suite grounded in what the system has actually broken on. A fix that clears the replay set but introduces a new wave of rephrasing or abandonment in the regression set is not a good fix. The validation criterion has to track implicit signal rates in the regression set, not just whether tasks nominally completed. Pairing runtime tracing with automated eval gates, scorers that grade agent outputs and can block a regression before it ships or flag a live quality drop, is the mature version of this pattern, and it turns replay from a one-off check into a standing part of the release process.
Closing the loop: making signal-to-backlog conversion a repeatable engineering process
Running this pipeline once against a single failure is investigative work. Running it continuously against recurring patterns is engineering discipline: a team either has a systematic process or is relying on whichever engineer happened to notice the problem that week. The full loop runs from production trace to signal detection to attribution to a backlog item with an attached replay set, then through a fix, then through validation, and into a promoted regression gate that feeds back into the next round of production traces. Production traces should feed automatic dataset curation on an ongoing basis, drift detection should track prompts and use cases over time rather than as a one-time audit, and alerts should route into incident management channels when quality slips, not only when latency spikes. An agent can keep improving its harness state, meaning its prompts, memories, tools, skills, and routing rules, while the underlying model stays completely frozen. Harness continual learning, or HCL, is the term used to formalize this as a distinct mode of improvement, separate from and complementary to weight-based retraining. Making the discipline repeatable requires four things: a consistent span schema applied across every agent deployment, a regular triage cadence that reviews signal pattern reports rather than waiting for an incident, a named owner for each failure category by harness layer, and a backlog policy where no item moves to done without a passing replay set behind it. Treating harness engineering with the same review gates applied to ordinary code is what separates teams that improve agent quality systematically from teams that only ever react to the incident in front of them. Moda operationalizes this loop directly: it ingests production traces, surfaces recurring behavioral failure patterns, attributes each one to the specific harness component responsible, generates a concrete and reviewable fix, and validates that fix against historical traces before recommending what to ship, so the pipeline runs continuously rather than depending on manual investigation every time something goes wrong.